I gave a junk-pile eyes, ears, and a voice
The machine these words were written on has no case. Two old GPUs, a wall of second-hand drives, a factory button for a power switch. Over a few nights it learned to see, hear, think, and talk back. Every model runs on the machine itself, with nothing in the cloud. This is how the frankenstein got its senses.
| The junk | What it became |
|---|---|
| No case at all | open-air on the bench, a body you can reach into |
| Two old GPUs | run the local LLM, Whisper STT, and a neural voice, on the metal |
| 20 assorted second-hand external drives | the memory |
| A pile of Plantronics ADACs from an abandoned office | the audio lanes: speaker + mics over USB |
| An old factory start/stop button | the power switch |
| Altec Lansing speakers, early '90s | the mouth |
| A mic from my grandfather's garage, '60s | an ear |
| A Realistic condenser mic, Salvation Army | another ear |
| A baseless Salvation Army monitor | the display |
| Scrounged Logitech webcams | the eyes. And, it turned out, the best ears too |
The premise
The house rule here is Anti-Cloud. Host Local, Think Global. For Meatball's senses that means no cloud APIs and no someone-else's computer. The speech recognition, the voice, and the brain all have to live on the same open-air motherboard the cameras are zip-tied next to. The fun constraint: do it on hardware nobody wanted.
Eyes
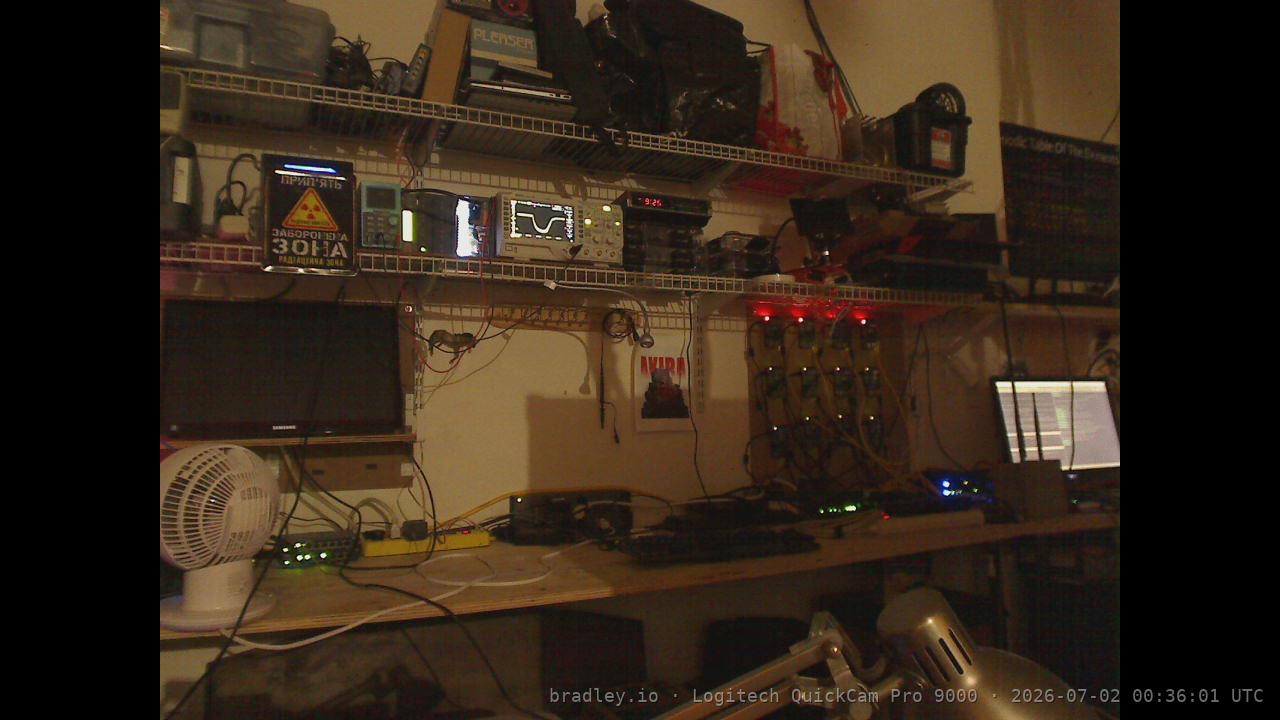
First the eyes. A scrounged Logitech BRIO grabs a frame once a minute on a timer, and the site serves the latest one from its own address. It is the same pipeline behind /eyes and /eyes.png. A second webcam joined later, the two trading off every minute. The box could see. It could not yet say anything about it.
A mouth and an ear
The voice came from two local services: faster-whisper for speech-to-text, and Microsoft's VibeVoice for a neural mouth. It streams audio straight to the speaker, so the first word lands in about a third of a second. The brain is a small Ollama model. A tiny toolkit ties them together: listen, say, converse, and a narrate that pipes a camera frame through a vision model so the box can describe what it's looking at. On paper, done.
The saga
On paper. In the room, the speaker was silent and the mic was deaf, and it took an embarrassing while to learn why. Cheap USB audio dongles lie. Their analog-to-digital chip carries a constant DC offset that reads as a healthy -35 dBFS signal. I spent an hour convinced a microphone was "live" when I was staring at a flat electrical bias, not a sound.
The thing that cracked it was a radio. Switched it on, recorded; switched it off, recorded. The two were identical. A radio playing in the room moved the meter not at all. The mic wasn't quiet. It was stone deaf. Then the speaker. I'd guessed which of three identical dongles it was from capture levels, and I was wrong. Here is the first trap: a speaker crosstalks into its own input and masquerades as the hottest mic in the rack. You cannot find a speaker by listening to it electrically. You have to play a sound and ask a human, or a known-good ear, which one made noise. A round of "how many beeps did you hear" finally pinned it.
The two traps
The breakthrough was hijacking the webcam microphones. The BRIO's array mic (already in the room as an eye) turned out to be the best ear in the building, picking up the room 40 dB louder than the dead dongles and transcribing the box's own voice near-perfectly. The grandfather's garage mic and the thrift-store condenser are wired in beside it.
And the second trap, the mirror of the first: a dead mic reads the quietest floor, because it's capturing nothing. Rank microphones by "lowest noise" and you will confidently select the most broken one. You have to rank them by how well they hear a known sound, by response, never by silence.
Calibration, the whole story in 30 seconds
Both traps now live in one script. calibrate.sh uses the sensitive camera mic as a reference, so nobody has to touch anything. It plays a tone out of each output and listens for which one comes back: that is the speaker. Then it plays a tone out of that and ranks every microphone by how well it hears it: the best is the ear. It checks itself by having the box speak a phrase and transcribe it. It samples the room to set a noise gate, saves which device is which by USB port, and announces, out loud, that it's done. The hour-long manual ordeal now takes half a minute, and it survives the next time the dongles get shuffled.
What it does now
It sees, hears, thinks, and answers. Speak and the BRIO catches it, Whisper transcribes, the local model thinks, and the Altec Lansings (older than most of the software stack) say something back in about a second. Ask it what it sees and it narrates the room through a vision model. Leave it alone too long and it gets bored and says so, then opens a mic to see if anyone's there. A frontier-AI loop running entirely on a caseless pile of other people's cast-offs.
That's the whole point. The cloud would have made this trivial and forgettable. Doing it on a grandfather's microphone and a Salvation Army monitor with no base makes it mine, and proves the interesting part of this era isn't the data center. It's how little hardware you actually need.